Reliability & Scale · Engineering blueprint
Fault-Tolerant Systems for Mission-Critical Operations.
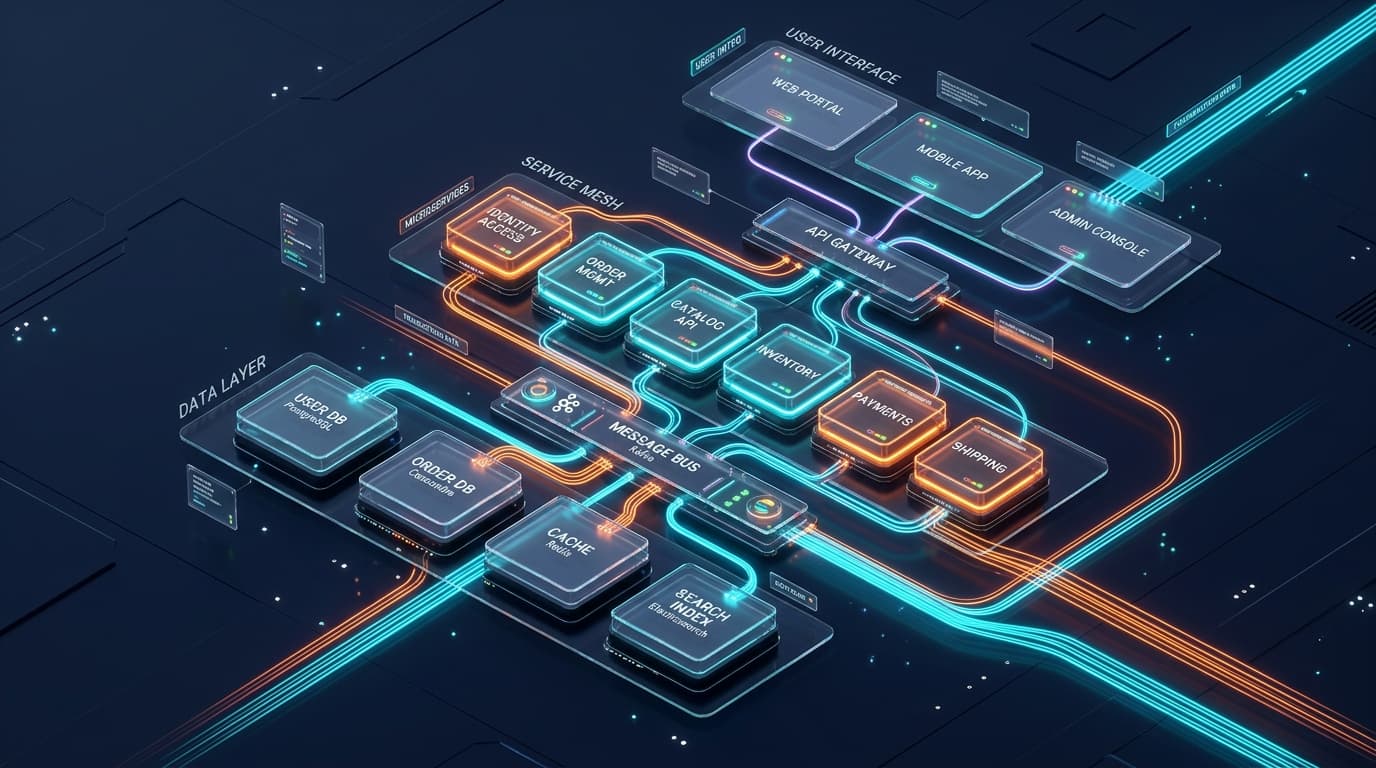
Engineering high-concurrency systems equipped with automatic failover, geo-redundancy, and self-healing infrastructure.
Architecture motto
“Five-Nines Reliability for Mission-Critical Platforms.”
Platform engineering, APIs and high-availability delivery.
Autonomous Agent Tool Execution Engine
Why Syntamatic · For every company size
How High-Availability Platform Engineering works for your organisation
Whether you run a global enterprise, a scaling mid-market business, or a focused SMB — Syntamatic designs delivery, governance and technology to match how you actually operate.
Fortune & regional enterprises
AI-embedded systems for complex operations
Enterprise programmes for High-Availability Platform Engineering with integration, security and accountable SLAs.
- Architecture-first delivery with accountable SLAs
- Private AI, RAG and agent systems under your control
- Integration across ERP, data and workforce platforms
Legacy Status Quo vs. Syntamatic AI-Native State
In-depth architectural comparison, workflow flowchart breakdown, quantified performance metrics, and C-Suite strategic impact model for High-Availability Platform Engineering.
Manual & Fragmented Operations
Server crashes causing unplanned downtime and lost revenue.
Legacy environments rely on disconnected spreadsheets, manual copy-pasting across legacy ERPs, and batch file drops. This creates single-point human dependencies, data corruption, and operational vulnerability during volume surges.
- Manual re-entry and processing backlogs
- Slow monolithic release schedules
- No real-time operational visibility
Autonomous & AI-Native Execution
Self-healing Kubernetes clusters failing over automatically in under 5 seconds.
Syntamatic orchestrates governed AI agent workflows, intelligent document processing, and secure API gateways directly into your core systems—executing workflows with complete audit traceability.
- Chaos Engineering & Resiliency Testing
Operational challenge
Costly Outages & System Crashes
Unplanned downtime in core transactional systems results in lost revenue, compliance fines, and reputational damage.
Why Syntamatic
Resilient Chaos-Tested Infrastructure
Engineers multi-region Kubernetes clusters, distributed database replication, and automated disaster recovery failovers.
Guarantees continuous uptime and zero data loss for high-volume transactions.
Capabilities & stacks
Chaos Engineering & Resiliency Testing
Simulating node failures to verify automatic self-healing.
- Failover Playbook
- Resiliency Audit Report
Stack highlighted for High-Availability Platform Engineering
High-frequency transaction processing engine with zero loss guarantees.
SMB & Growth ROI Estimator
Frequently asked
How do you guarantee high availability?
Through multi-region active-active deployments, automatic load balancing, and distributed databases.
Move AI From Ambition to Operation.
Tell us about your enterprise, your priority and your timeline. We will route your request to the right industry and capability lead — and respond with a clear next step.